The Hard Cap: Why "AI Credibility" Can't Score Above 35 Without a Revenue Line
When a scoring rubric lets fluent narrative move the same dial as hard disclosure, the more persuasive management team always wins, so LacunaIndex clamps specific score dimensions to a fixed ceiling until named disclosure items exist, sector by sector, regardless of how the story reads.
The story is always more fluent than the disclosure
Every buy-side equity diligence analyst — the professional who screens a company's public filings and communications before recommending an investment — knows the pattern. A management team describes an "artificial intelligence (AI) transformation" or a "flagship enterprise win" with total command of the room. The chief executive officer's language is specific, confident, unhedged. And when you go looking for the number underneath it — the actual revenue line, the actual customer name, the actual retention rate — it isn't there. The 10-K, the annual report a public company files with the U.S. Securities and Exchange Commission, is silent on it. The narrative got ahead of the disclosure, and nothing in the room forced it back.
Most scoring frameworks, human or automated, are vulnerable to this because they score the narrative and the evidence on the same dial. A sufficiently well-told story nudges the same number that hard disclosure would. LacunaIndex's forensic scorecard — the rubric-based methodology behind its issuer reports — handles this with a mechanism worth borrowing regardless of what platform you diligence on: it will not let a dimension score rise past a fixed ceiling until specific, named disclosure items exist, no matter how the narrative reads.
Caps that only ever pull a score down
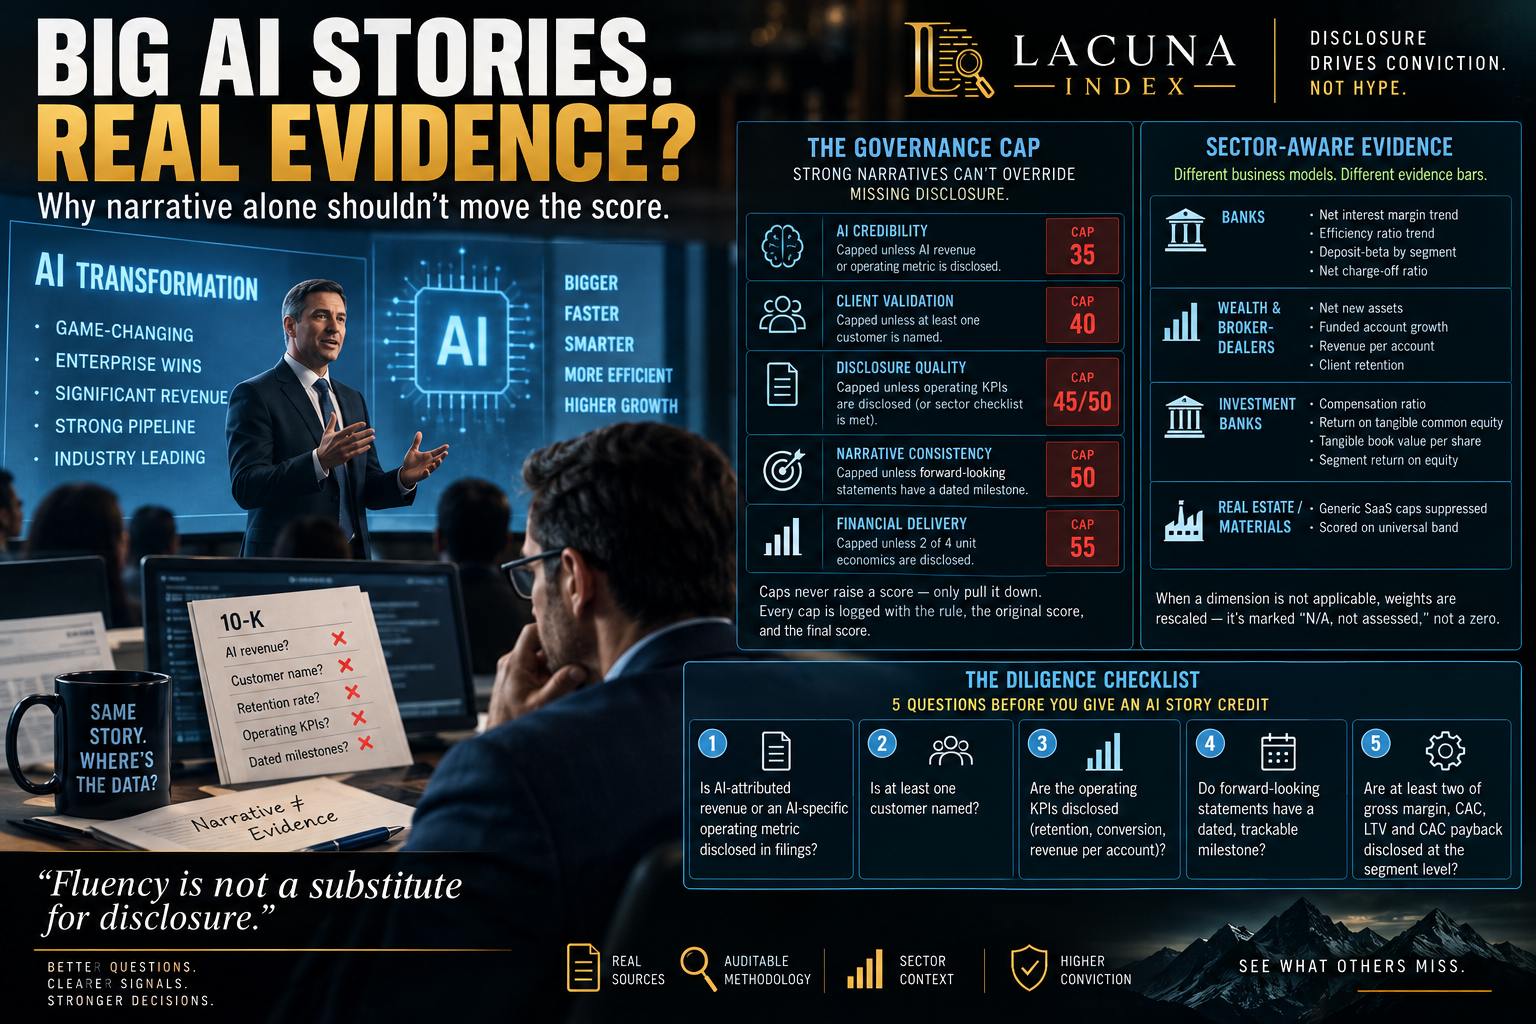
The mechanism, called a governance cap, is a deterministic post-processing step. The underlying model returns its rubric subscores for each of the scorecard's dimensions — financial delivery, executive accountability, narrative consistency, and so on — and only after that does a fixed registry of rules check whether the structural evidence behind each claim actually exists. If it doesn't, the dimension's score is clamped down to a ceiling, regardless of how high the narrative-driven subscore came in. Caps never raise a score, only lower one, and when several rules fire on the same dimension, the lowest cap wins.
The current registry includes:
- AI credibility capped at 35 — unless the issuer attributes actual revenue, or at least a disclosed operating metric, to the AI initiative being described.
- Client validation capped at 40 — unless at least one customer is named in support of the claim, rather than an aggregate customer count.
- Disclosure quality capped at 45 — unless operating key performance indicators (KPIs, the recurring operating metrics a business reports — retention, revenue per account, conversion rate) are publicly disclosed; capped at 50 if three or more items from the sector's expected-evidence checklist are simply missing.
- Narrative consistency capped at 50 — unless forward-looking statements carry a concrete, trackable date rather than an open-ended aspiration.
- Financial delivery capped at 55 — unless at least two of four unit-economics disclosures exist: segment-level gross margin, customer acquisition cost (CAC, what it costs to win a customer), customer lifetime value (LTV, what that customer is worth over time), and CAC payback period.
Each firing rule is written to a governance log that ships in the report appendix, naming the exact rule, the pre-clamp score the model returned, and the post-clamp ceiling. The reasoning behind "why is this a 44 and not a 51" is not a black box — it is one line, traceable to a named disclosure gap.
One bar doesn't fit every business model
A cap tuned for a software company will misfire on a bank. Unit economics such as CAC and LTV are meaningless for an institution whose business model runs on net interest margin and deposit retention, not per-customer acquisition spend — and a rigid cap that ignores that would systematically underscore an entire sector regardless of disclosure quality.
LacunaIndex resolves this with a second, sector-aware layer sitting on top of the cap registry: a governance table keyed by industry classification that substitutes the correct evidence bar before the generic cap ever fires. For banks, financial delivery is instead judged against net interest margin trend, efficiency ratio trend, deposit-beta by segment, and net charge-off ratio by portfolio — and client validation is judged against primary-bank relationship share, deposit retention, and named institutional mandates rather than named software customers. Broker-dealers and wealth platforms get their own substitute set (net new assets, funded-account growth, revenue per account); investment banks get another (compensation ratio, return on tangible common equity, tangible book value per share, segment return on equity). For sectors where the entire software-as-a-service evidence frame is structurally inapplicable — real estate, materials — the generic cap is suppressed outright and the dimension is scored on a universal band instead.
When a dimension is marked not applicable this way, its weight doesn't just vanish from the scorecard. The remaining dimensions in that pillar are proportionally rescaled so their weights still sum to the pillar's original total — the scorecard reads "N/A, not assessed" rather than silently scoring a zero, which would misread as "assessed and failed." A related discipline shows up one layer up: the confidence band attached to the report's overall verdict is deterministically capped to the weaker of the execution and vision sections' evidence bases, so a headline "high confidence" call can never sit on top of a chain of claims that were mostly unverified.
The transferable checklist
None of this requires LacunaIndex's specific rubric to be useful to a diligence process built elsewhere. The transferable idea is pre-registering, before you read a single transcript, exactly which disclosure items are allowed to move which score — and refusing to let fluency substitute for any of them. For an AI-native growth story specifically, the checklist that governs whether the "credibility" conversation is even allowed to move a score is short and concrete:
- Is AI-attributed revenue, or at minimum an AI-specific operating metric, disclosed anywhere in the filings — not just referenced on the earnings call?
- Is at least one customer named in connection with the claim, rather than an aggregate count?
- Are the operating KPIs behind the claim (retention, conversion, revenue per account) publicly disclosed?
- Do forward-looking statements carry a dated, trackable milestone rather than an open horizon?
- Are at least two of segment gross margin, CAC, LTV, and CAC payback period disclosed at the item level, not folded into a consolidated aggregate?
If the answer to a question is no, the honest move is not to average it into an otherwise strong narrative — it's to cap the conclusion that depends on it, write down exactly why, and revisit it the day the disclosure changes.
LacunaIndex's forensic scorecard and its governance-cap registry are part of the platform's live methodology on the crescentic-llc/lacunaindex codebase and are versioned — caps and sector overrides can change between methodology releases, and a report always carries the version stamp it was scored under.